What Is NVIDIA Flare and Can It Run on Your Machine?
NVIDIA Flare: a model package built ahead, served by one machine and linked across two small machines

NVIDIA published a local inference server called Flare NVIDIA put a local inference server called Flare on GitHub on October 20, 2026, under the repository name flare-local-inference (Mike Gannotti's walkthrough, October 21, 2026). It runs on two machine families only: the GB10 chip in a DGX Spark, and the workstation Blackwell cards in the RTX … Read more
GPU Unlock: 2X Tensor Speed, but What Do LLMs Get?

Qwen 3.8 Flash Next on an RTX 3090: the Founders Edition card beside the article title

What is the GPU unlock, and which graphics cards does it speed up? The GPU unlock is an open-source Linux kernel module that switches the half-rate tensor math of a GeForce card back to full rate. It comes from Zagitta, covers the RTX 30 series chips GA102, GA103, GA104 and GA106, and a fork from … Read more

Muse Spark Open VRAM Requirements: What Can Hold It

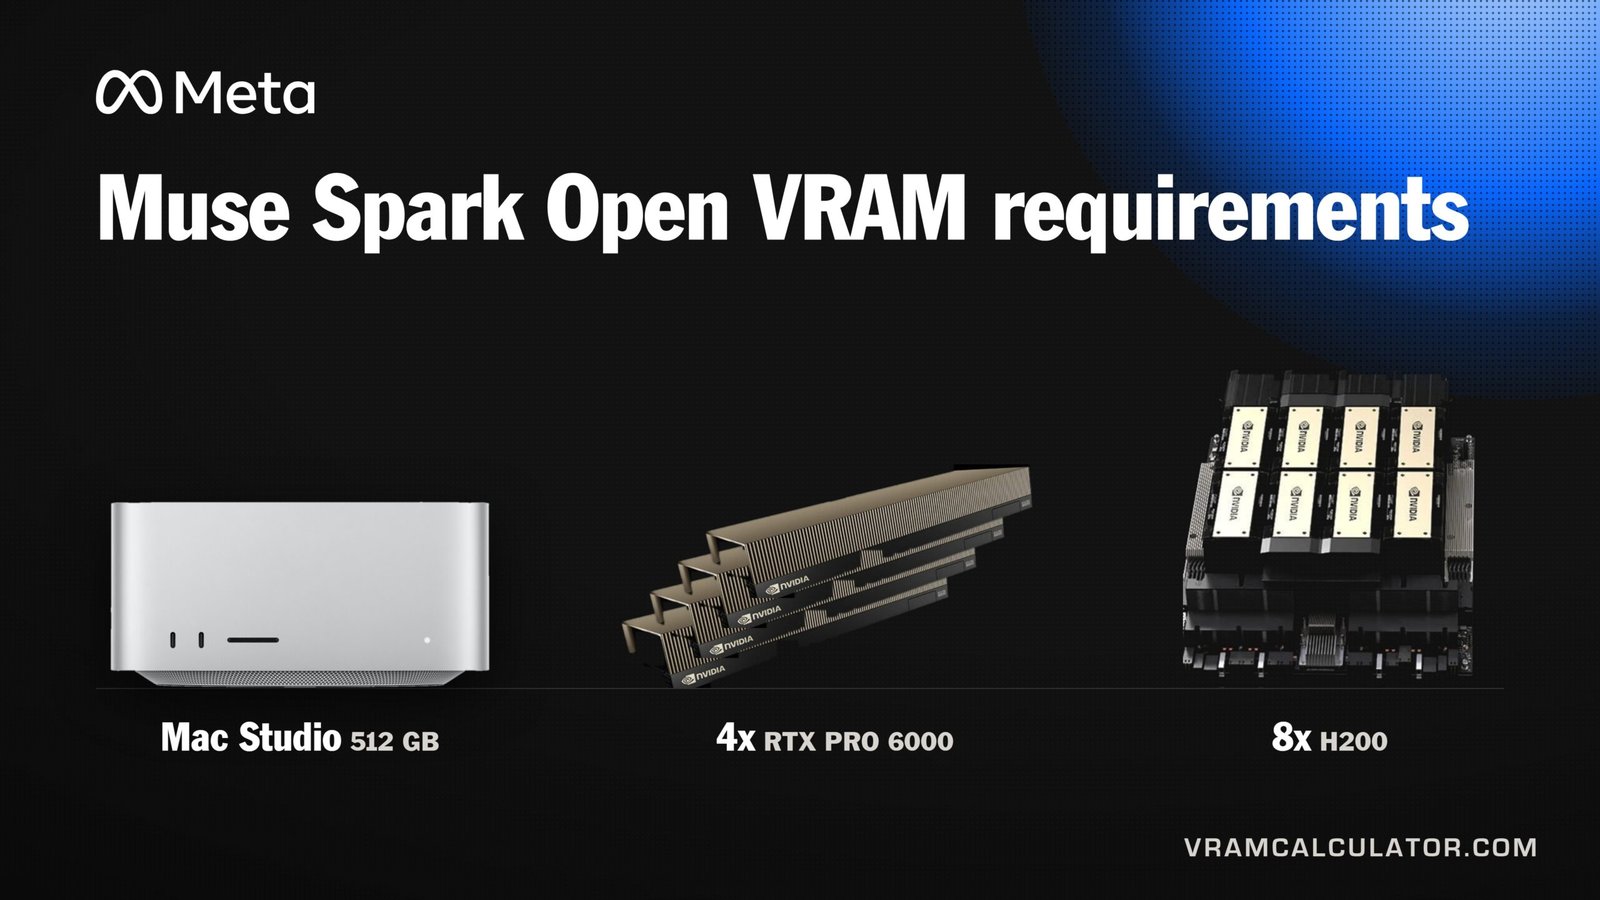
Muse Spark Open VRAM requirements: a 512 GB Mac Studio, four RTX PRO 6000 cards and an eight-GPU H200 board, the machines that hold Meta's model

How Much VRAM Does Muse Spark Open Need? 293.9 GB at the smallest mainstream build (Unsloth's Q2_K), 476.7 GB at Q4_K_M and 502.5 GB for Meta's own NVFP4 build, each with an 8K cache and llama.cpp overhead. Muse Spark Open is Meta's 816B-A42B mixture-of-experts model, released on 15 October 2026, and the repo's own safetensors … Read more

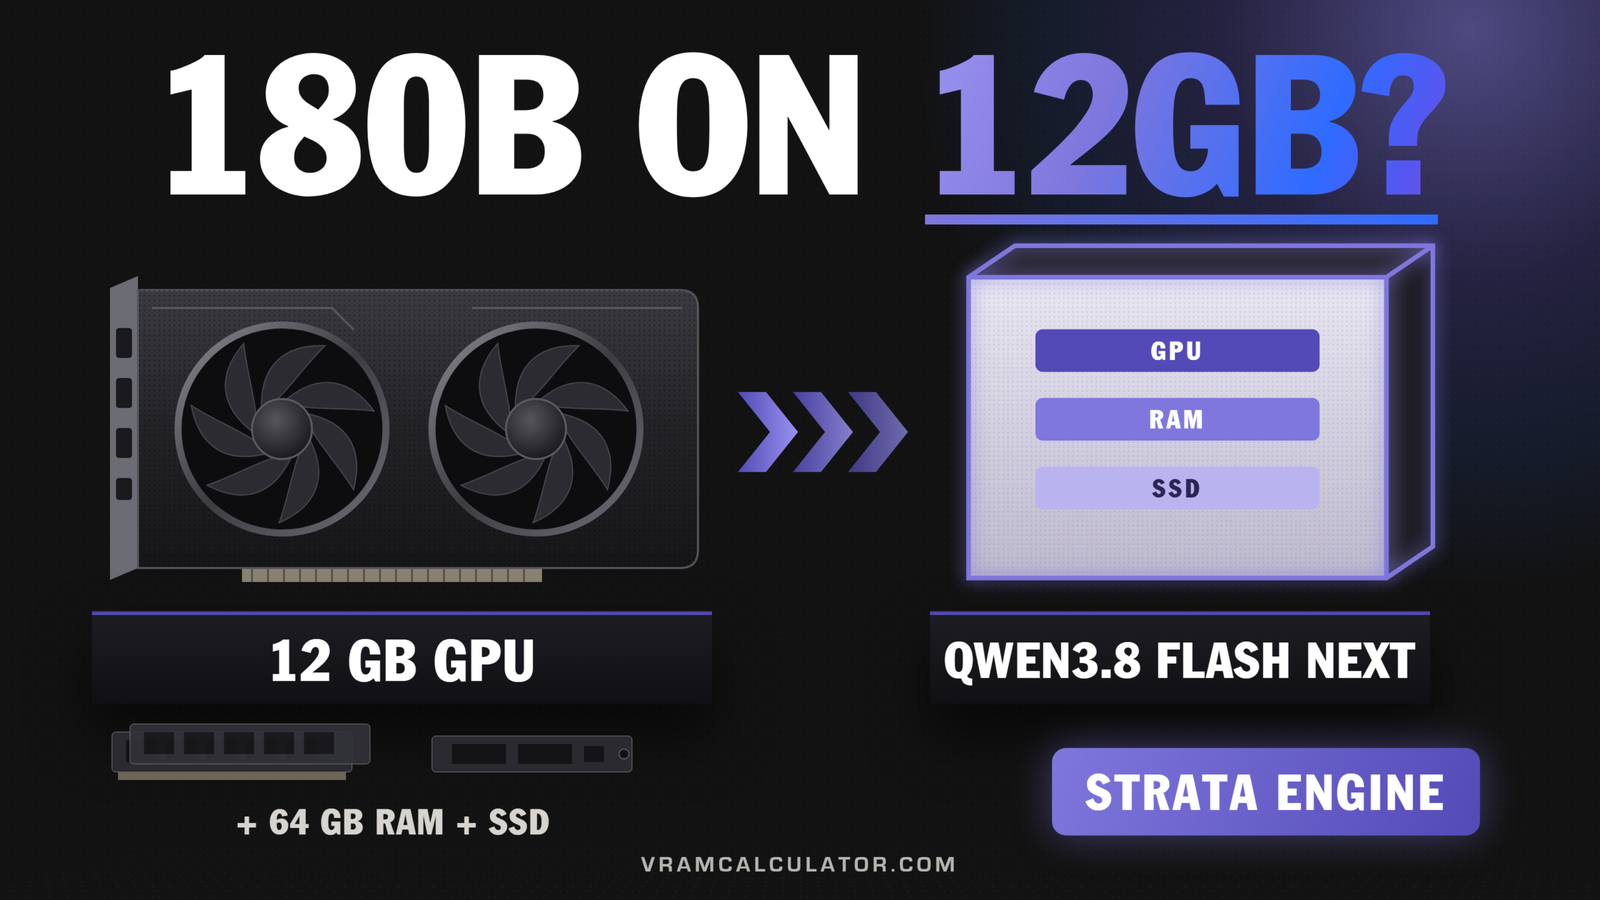
Strata: Running Qwen 3.8 Flash Next on a 12 GB Card

Strata Qwen3.8-Flash-Next, Strata inference engine, Qwen3.8-Flash-Next 12GB, Flash-Next gaming PC, Strata RAM requirements, GSQ-RCO GGUF, run 125B model 12GB GPU

What Strata is Strata is an open-source engine that runs Qwen 3.8 Flash Next, a 180-billion-parameter model built for servers, on one gaming card with 12 to 24 GB and 64 GB of system RAM. It comes from Niko Veit (@coldniko), under the MIT licence, runs on NVIDIA and recent AMD cards on Linux and … Read more