Rent a GPU for AI: Run High-End Models Before You Buy
try local ai without buying a gpu, what gpu do i need to rent for llama 70b, buy vs rent gpu for local llm, rent gpu by the hour to test ai, how much vram to run ai in the cloud, nvidia brev

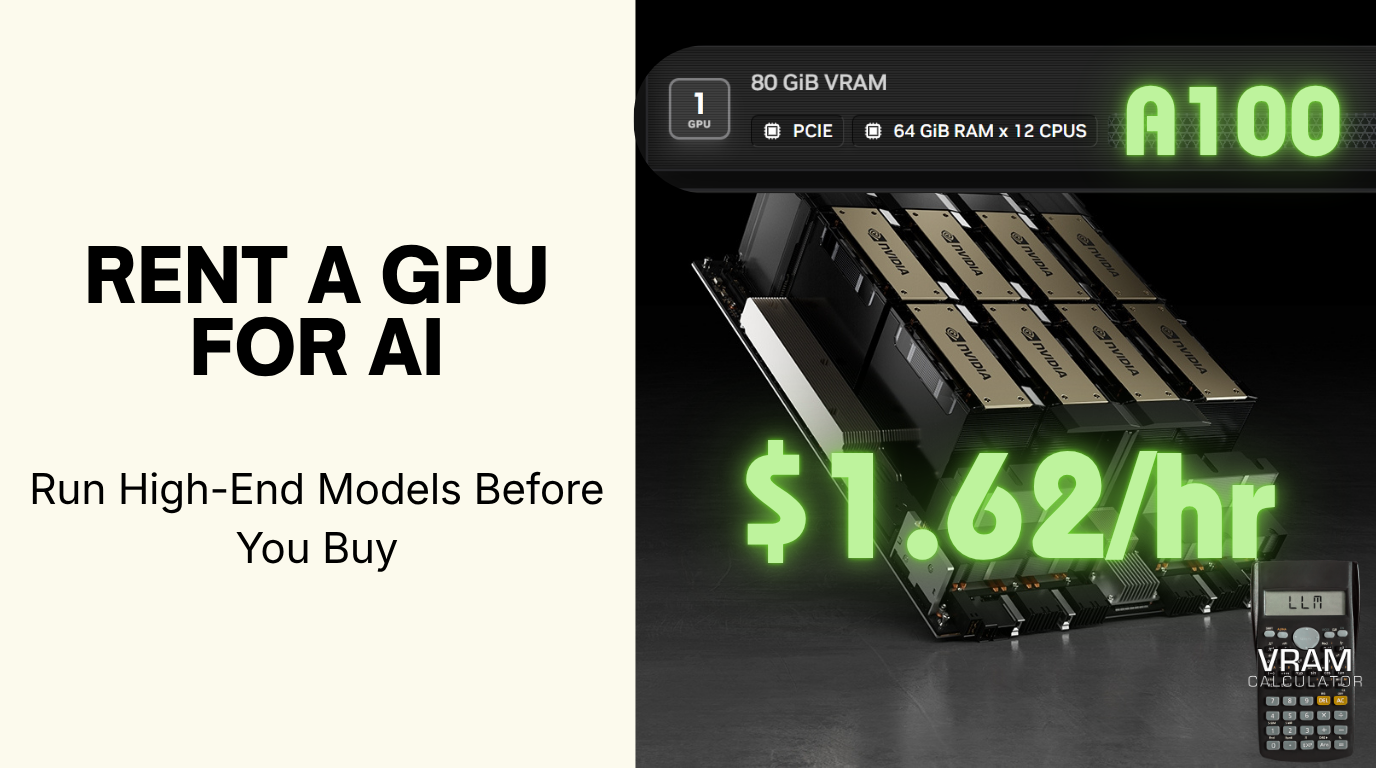
Can You Run High-End AI Without Buying a GPU? Yes. And it costs less than lunch. Running a 70-billion-parameter open-source model at home sounds like a five-figure hardware project, so most people never try. That belief is the single biggest reason capable developers stay on the sidelines of local AI. It is also wrong. As … Read more
Local AI API Server: Setup, Real Limits, and the Fix

jan ai local api server, on-device ai api advantages, run llm locally comparison, integrate ai without cloud, ollama context length, opencode ollama setup

How Do You Turn a Local LLM Into an API Server? Run it through Ollama or Jan, both of which expose an OpenAI-compatible endpoint on your own machine: http://localhost:11434/v1 for Ollama, http://localhost:1337/v1 for Jan. Point any tool built for the OpenAI SDK at that URL with any placeholder API key, and it behaves exactly like … Read more

What LLM Can I Run? Check Your GPU in Seconds for Free

What LLM Can I Run on My GPU?

VRAMCalculator.com What Can My GPU Run? Your VRAM pool 0 GB GPU brand NVIDIA AMD Intel Your GPU Total VRAM / unified memory, GB Number of cards Context window 8,192 tokens 2K4K8K16K32K64K128K256K512K1M KV cache precision Inference backend Same math as the model-first VRAM calculator: effective bits per weight, architecture-correct KV cache (including MLA compression), and … Read more

Kimi K3 VRAM Requirements: What 2.8T Actually Takes

kimi k3 vram requirements

How Much VRAM Does Kimi K3 Need? The short answer, now that the weights are public: the download alone is 1.56 TB, and that is the part that locks you out. The context window, counterintuitively, is nearly free. Moonshot’s launch post confirms a 2.8-trillion-parameter Mixture-of-Experts model shipping natively in MXFP4, and the published files measure … Read more

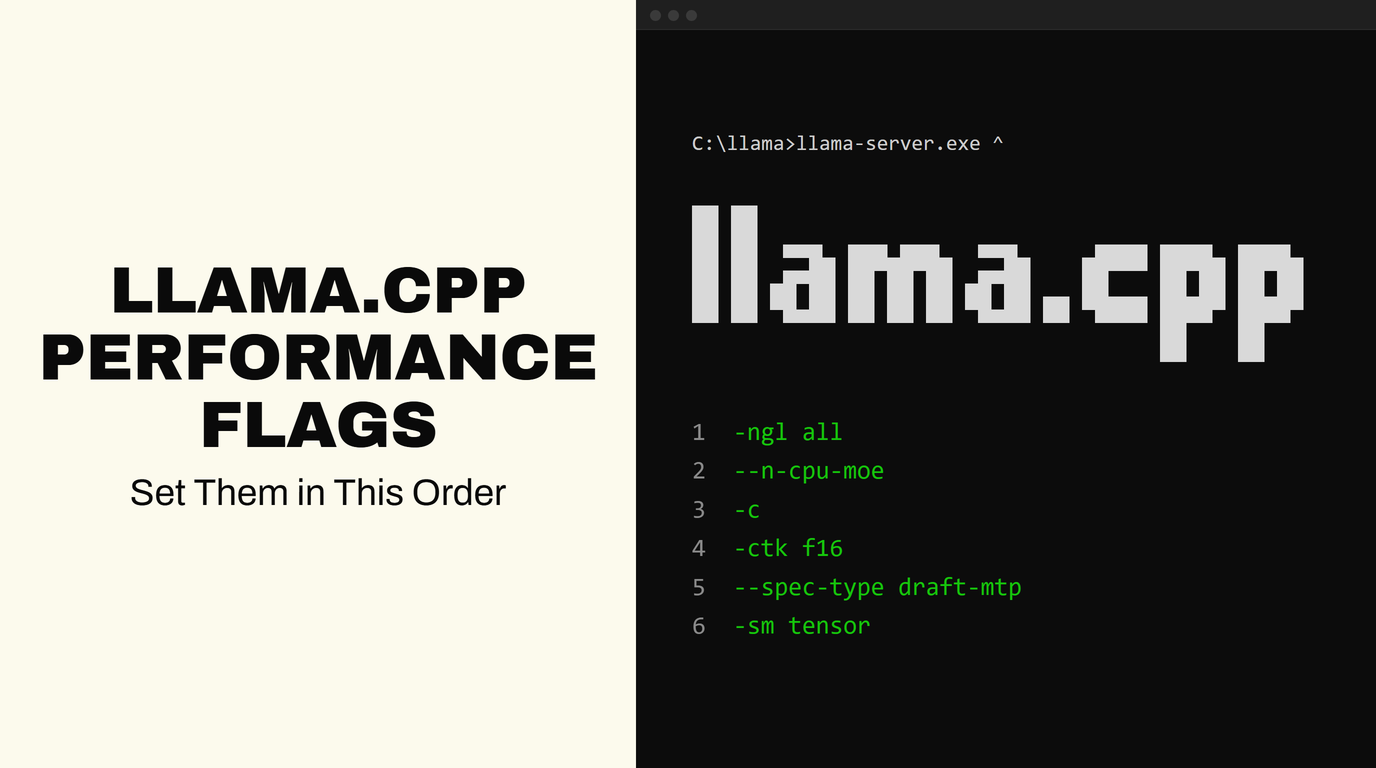
llama.cpp Performance Flags: Set Them in This Order

llama.cpp performance flags

Which llama.cpp performance flags matter, and in what order? Set them in this order: size the model first, then GPU layers, then MoE offload, then context, then the KV cache type, then speculative decoding, then multi-GPU split. Each step changes what the next one can do, which is why a flat list of twenty flags … Read more

Run 405B on 8GB VRAM? No One Has Published the Speed

run 405b on 8gb vram airllm speed, how fast is airllm, colibri llm, weight streaming llm, glm-5.2 744b, run llm from disk

Can You Really Run a 405B Model on 8 GB VRAM? Loading it: yes, demonstrably: AirLLM’s layer-streaming technique is real engineering. Running it at a published speed: nobody has shown that number. As of July 2026, no measured throughput figure, tokens per second, for Llama 3.1 405B via AirLLM exists in public: not in the … Read more

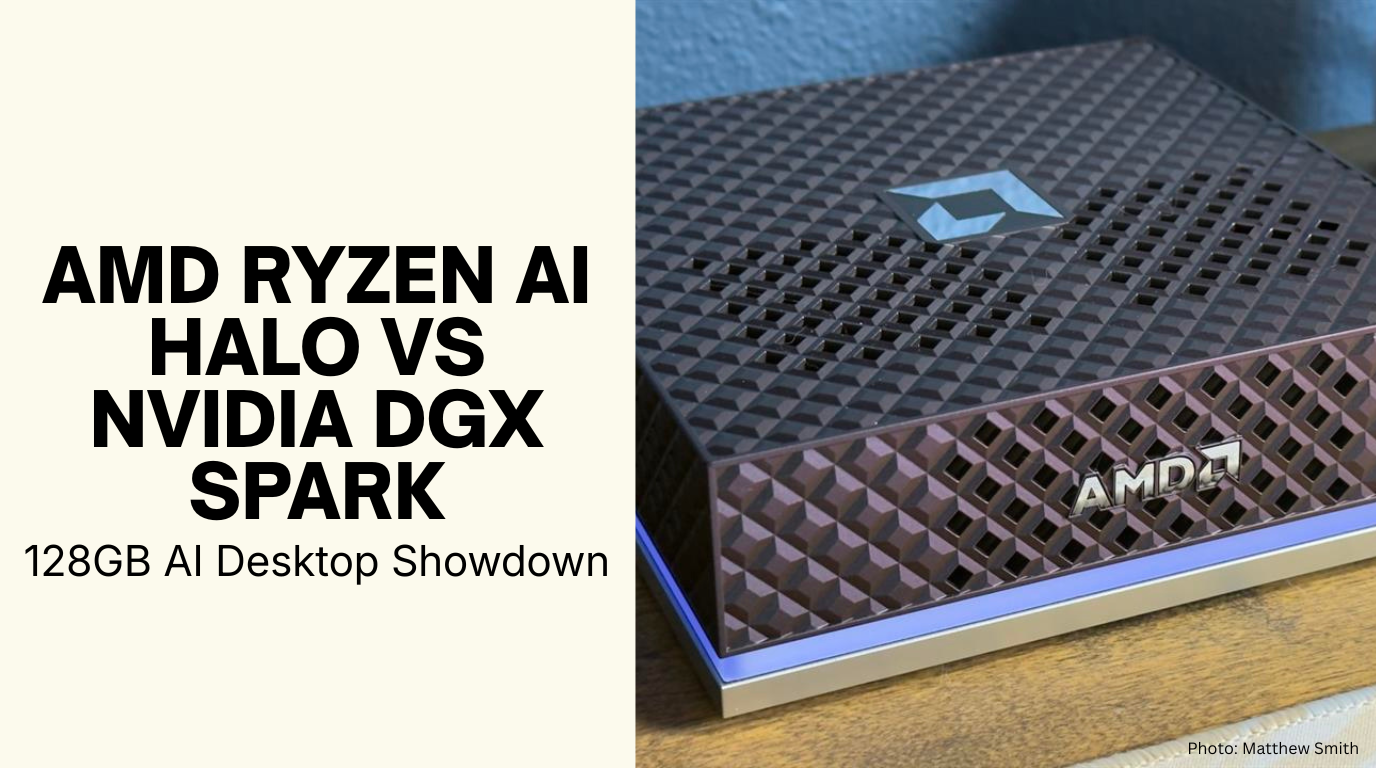
Ryzen AI Halo vs DGX Spark: 128GB AI Desktop Showdown

ryzen ai halo vs dgx spark amd ryzen ai max 395 local llm

AMD Ryzen AI Halo vs NVIDIA DGX Spark: The 128GB AI Desktop Showdown Which is better for local AI: the AMD Ryzen AI Halo or NVIDIA DGX Spark? The NVIDIA DGX Spark is better for pure AI inference workloads, delivering 2.7× to 13.4× higher token throughput than the AMD Ryzen AI Halo thanks to hardware … Read more

Local LLM VRAM Requirements: Which Models Fit Your GPU

local LLM VRAM requirements

What VRAM do you need to run local LLMs in 2026? Running local LLMs in 2026 requires a minimum of 8GB VRAM for 4B to 8B parameter models under Q4_K_M quantization. 16GB VRAM handles models up to 14B parameters comfortably, with Gemma 4 12B fitting natively including its multi-modal stack. Dense 30B+ models require 24GB … Read more