Ling 3.0 Flash VRAM: the 4-Bit Build Shipped Day One

ling 3.0 flash vram, ling 3.0 flash dgx spark, ling 3.0 flash gguf, inclusionai ling 3.0 flash, run ling 3.0 flash locally, ling 3.0 flash 124b, ling-3.0-flash vram

How Much VRAM Does Ling 3.0 Flash Need? 81.1 GB at the official FP4 build, or 86.2 GB at Q4_K_M, both including runtime overhead at an 8K context. Ling 3.0 Flash, published as inclusionAI/Ling-3.0-flash, is a 124B mixture-of-experts model with 5.1B parameters active per token, released on August 4, 2026 under an MIT license. The … Read more

DeepSeek V4 Flash on DGX Spark: Setup and Benchmarks

dgx spark deepseek v4 flash, run deepseek v4 flash 0731 locally, ds4-on-spark, dgx spark 128gb llm, deepseek v4 flash m3 ultra, dwarfstar ds4

How to Run DeepSeek V4 Flash on DGX Spark One command, and it fits on a single 128 GB node. curl -sSL https://raw.githubusercontent.com/entrpi/ds4-on-spark/main/install.sh | bash -s — –start That is the installer from Entrpi’s ds4-on-spark, an MIT-licensed Blackwell CUDA fork of the DwarfStar engine, built specifically for the GB10. It pulls the model, builds the … Read more

DeepSeek V4 Flash 0731 VRAM Requirements: 162 GB Measured

deepseek v4 flash 0731, run deepseek v4 flash 0731 locally, deepseek v4 flash 0731 gguf, deepseek v4 flash specs, deepseek v4 flash vs kimi k3, deepseek v4 flash dspark

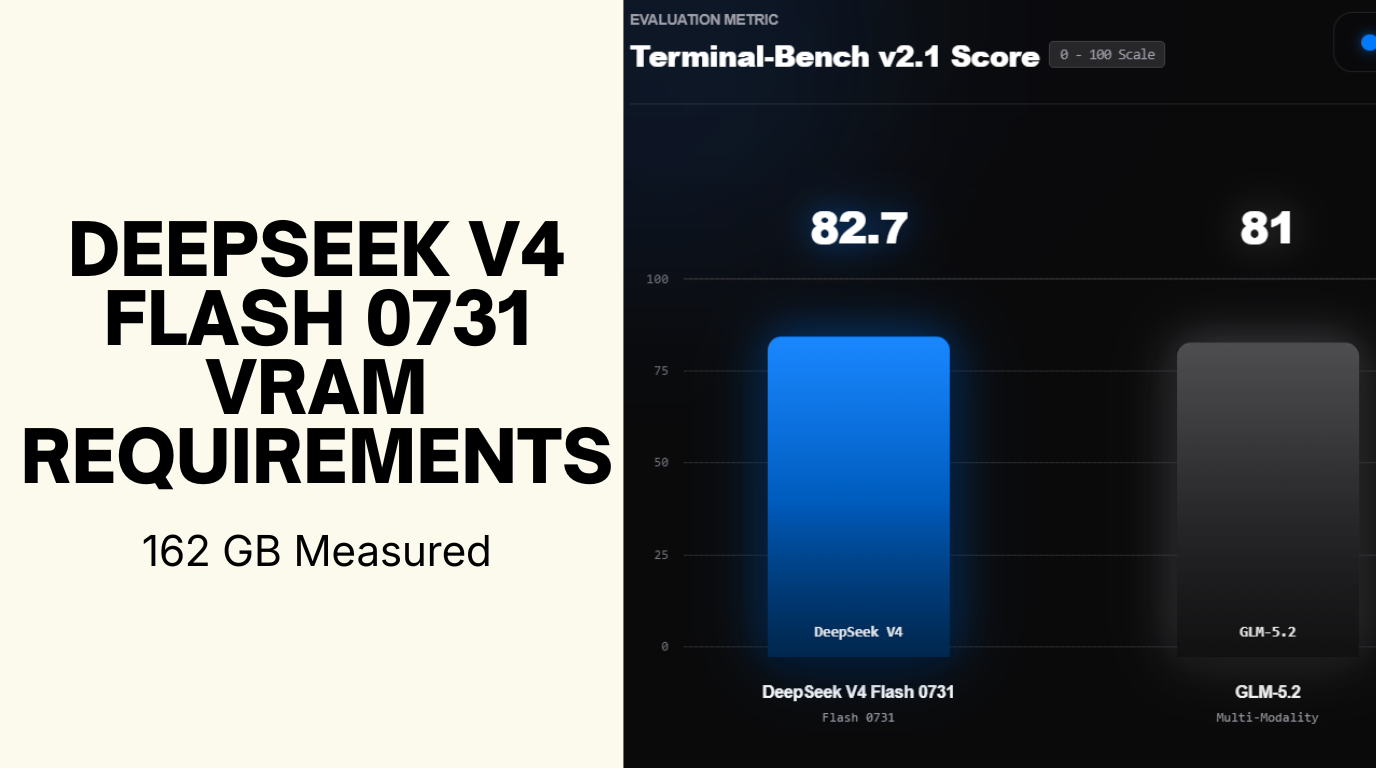
How Much VRAM Does DeepSeek V4 Flash 0731 Need? DeepSeek V4 Flash 0731 VRAM requirements land between 162 and 178 GB at 4-bit, and the spread is the interesting part. DeepSeek released the official DeepSeek-V4-Flash-0731 weights on 31 July 2026 under MIT, and Unsloth published GGUF conversions the same afternoon. The 4-bit build measures 155.1 … Read more

Run Kimi K3 Locally: What the 1-Bit Build Actually Does

kimi k3 1-bit gguf, kimi k3 mac studio, kimi k3 594gb, unsloth kimi k3, kimi k3 tokens per second, kimi k3 local hardware

We Said Kimi K3 Was Datacenter-Only. That Changed in Three Days. On July 27 we published what Kimi K3 requires and wrote that it was enterprise hardware regardless of quantization. Our calculator put full residency at 1,796 GB at Q4_K_M, which is five Instinct MI430X cards at 98% of their pool. Two days later Unsloth … Read more

Inkling VRAM Requirements: 975B and 276B Compared

how much vram does inkling need, run inkling locally, inkling 975b, thinking machines inkling requirements, inkling gpu requirements, inkling quantization, inkling hardware requirements, inkling model card

How Much VRAM Does Inkling Need? 680 GB at Q4_K_M with an 8K context for the 975B flagship, or 193 GB for Inkling-Small, which fits a single card. Those are the two numbers most people want, because Q4_K_M is the quantization almost every local deployment reaches for first. Inkling is Thinking Machines Lab's flagship open-weights … Read more

Chinese Open Weight Models: What Can You Actually Run?

chinese open weight models

Chinese Labs Own the Open-Weight Leaderboards. That Doesn’t Mean You Can Run Them. Open-weight model rankings in mid-2026 read like a list of Chinese labs: Z.ai’s GLM, Alibaba’s Qwen, DeepSeek, Moonshot’s Kimi. And the biggest release of the year has now landed. Moonshot published Kimi K3’s full weights on July 27, 2026, making it the … Read more

Run 26B on RTX 4060 (8GB)? What the Claim Leaves Out

rtx 4060 local llm, gemma 4 26b vram, 8gb vram large model, moe cpu offload, mtp speculative decoding llama.cpp, q4 kv cache, run large model low vram

Can You Really Run a 26B Model on an RTX 4060? Yes: and there’s video to prove it. On July 24, 2026, a tester running under the handle @analogalok posted a single RTX 4060 (the 8GB card, the one that sells for around $250) running Gemma 4 26B A4B, a 26-billion-parameter Mixture-of-Experts model, with vision, … Read more

Laguna S-2.1: 118B Model, 12GB Card. How CPU Offload Does It?

run 118b model on 12gb vram, n-cpu-moe llama.cpp, moe cpu expert offload, laguna s2.1 local, unsloth dynamic quant moe, poolside laguna

How Does a 118B Model Run on a 12GB GPU? It doesn’t: not the way you’d assume. Nobody is holding a 118-billion-parameter model entirely in 12GB of VRAM; that’s not physically possible at any reasonable quantization. What’s actually happening is expert offloading: most of the model’s weights sit in ordinary system RAM, and only a … Read more