Know what fits before you buy
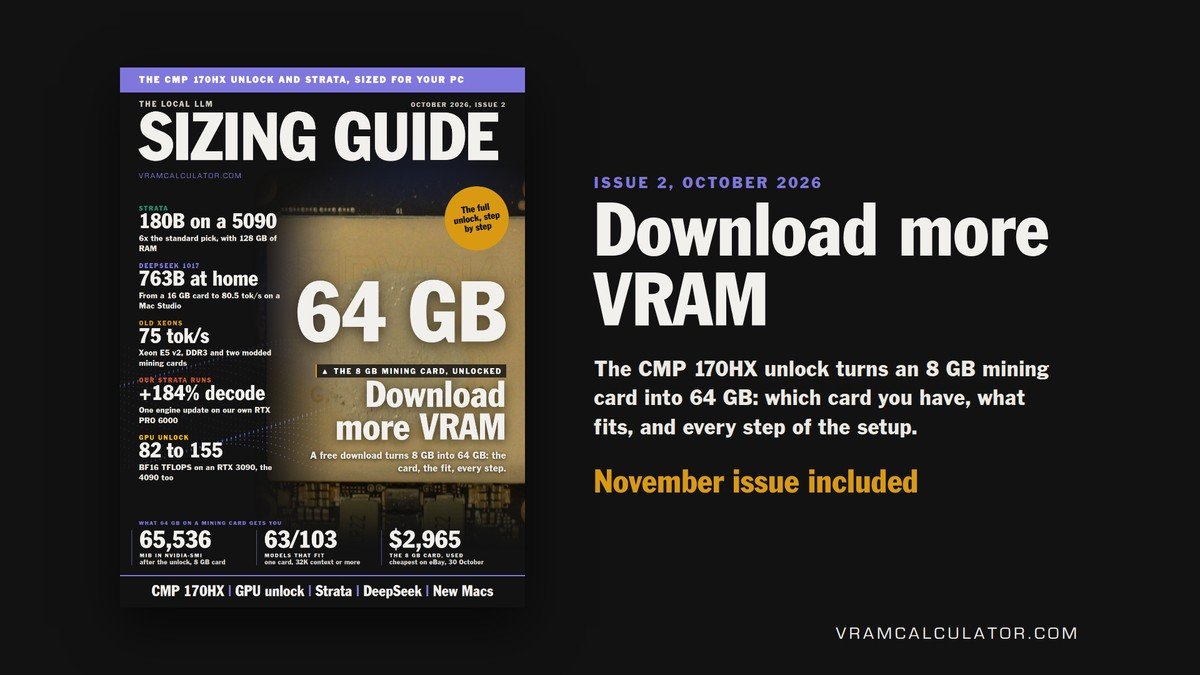
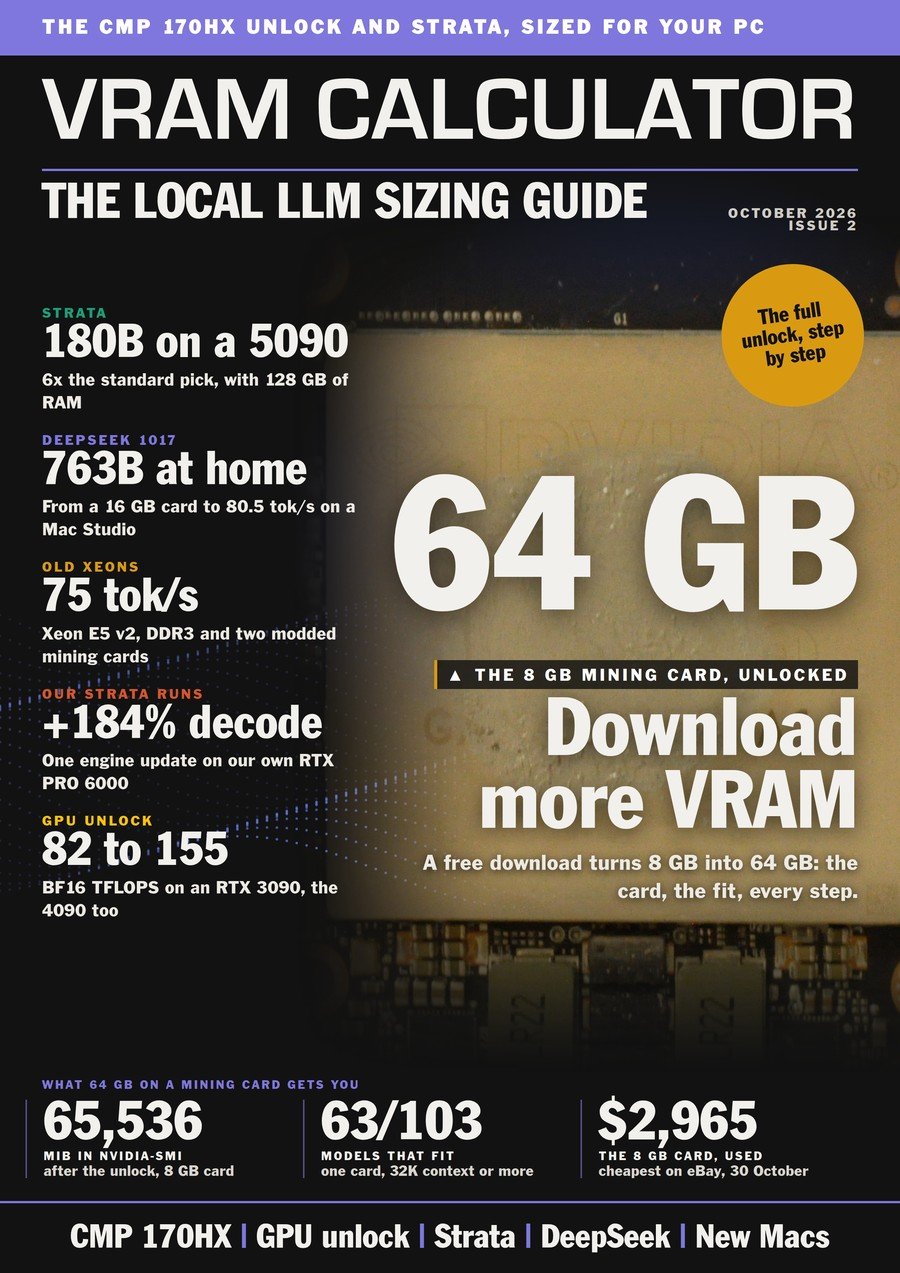
A GPU, a DGX Spark, a Ryzen AI Max machine or a Mac Studio is a purchase you make once. The Local LLM Sizing Guide shows what each one really runs before you spend: every model we size, on every machine from 8 GB to 512 GB, with the best quantization and the context it really holds. Issue 2 leads with the CMP 170HX unlock, an 8 GB mining card with 64 GB of memory, and Strata, a 180B model on an RTX 5090 with 128 GB of RAM.
From $9 a month. A vector A4 PDF, in your Whop library or by email. Card through Whop, or crypto. Every purchase includes the September issue and the next one.
Other calculators guess your context. This guide reads it.
of KV cache, guessed from the parameter count
what llama.cpp actually allocates
Qwen 3.8 27B at 64K of context: the guess is 7.5 times too high. Enough to send you shopping for memory you do not need, or to rule out a card that runs your model perfectly well.
Everything you need before you buy.
Download more VRAM: the 64 GB mining card
The CMP 170HX unlock turns an 8 GB mining card into 64 GB. Which card you have, what the unlock changes, what fits on one, two and four of them, and every step of the setup, with prices from listings you can buy.
after the unlock
card at 32K context
eBay, 30 October
Every model sized by the engine behind our calculators, at 32K of context or more.
A 180B model on an RTX 5090
Strata's own planner, card by card and RAM by RAM, on a PC and on a Mac, and every cell of our own Strata runs on an RTX PRO 6000.
Every machine, measured
From a 16 GB card to four RTX PRO 6000: the files, the engines, and what each machine writes per second.
82 to 155 BF16 TFLOPS on an RTX 3090
From one kernel module to the RTX 20, 30 and 40 series, and what it does, and does not do, for a local LLM.
75 tok/s on old DDR3 Xeons
No AVX2, DDR3 and two memory-modded mining cards: how Strata reached the cheapest servers, and what such a box costs now.
Qwen 3.8 27B on a 16 GB card
Best fit UD-Q2_K_XL, 11.75 GB. Then the context it holds with each cache type:
Twice the context from one setting. Every model on every tier is laid out like this.
Sharp on screen. Clean on paper.
PDFHigh-resolution vector PDF- A474 pages in Issue 2, laid out like a magazine
- VectorText, tables and charts stay sharp at any zoom
- 300 dpiPhotos at print resolution, so it prints cleanly at home
- YoursEvery issue you receive is yours to keep
Issue 2 now, with September and November included.
Card payments through Whop. Your issues arrive by email and in your Whop library.Paid through NOWPayments. After paying, email admin@vramcalculator.com your payment ID so we know where to send your issues.
Subscription
Every issue as it comes out
- Issue 2 and the September issue now, then every month
- Vector A4 PDF, sharp on screen and on paper
- The month's releases, sized, with measured runs credited
- Every correction counted, every issue
Single issue
Issue 2, September and November
- Issue 2, October 2026
- The September issue, included
- The November issue, included
- Vector A4 PDF, yours to keep
- No subscription
Before you buy
How is this different from the free calculator?
The calculator answers one model on one card per query. The guide lays out every model on every tier at once, with the context each cache type buys. It also follows the month's models and engines, prices hardware from listings you can buy, and carries our own measurements, in one document you keep.
What format is it?
A PDF in A4. Text, tables and charts are vector, so they stay sharp at any zoom on any screen, and the photos are at print resolution, about 300 dpi, so it prints cleanly on A4 at home. Issue 2 runs to 74 pages. You keep every issue you receive.
When do I get it?
Card buyers get Issue 2 and the September issue in their Whop library the moment they pay; crypto buyers get both by email once they send their payment ID. A new issue comes out on the last day of each month, and whenever you buy, the next issue is included.
Which cards does it cover?
Every tier from 8 GB to 128 GB: one reference card per tier, with every other card of the same memory listed and any difference stated. Beyond that, eight unified-memory machines side by side, from the 64 GB RTX Spark laptop chip to the 512 GB Mac Studio.
Will the model really load at the size you give?
Yes. Outside the Strata chapters, every fit is the whole model in your card's own memory, weights, cache and runtime all counted, so it loads at the size we give.
Can I pay in crypto?
Yes. Switch the plans above to crypto: the subscription is 3 months upfront for $27, the single issue $24.90. The guide is delivered by email, the same as a card purchase.
Stop guessing what fits.
Issue 2 is out now, with the September and November issues included.